Server side tracking routes analytics and ad data through a server you control before it reaches vendors like Google Analytics or Meta, instead of sending it straight from the browser. It improves data accuracy, gives you a place to enforce privacy rules, and cuts the number of scripts loading in a visitor’s browser. Sites juggling several vendor endpoints, advertisers with strict consent requirements, and high-volume commerce stores tend to benefit most.
TL;DR:
- Server-side tracking consolidates data routing through your own server, reducing the number of browser scripts and improving page load speed.
- It involves a self-hosted or cloud-deployed container that normalizes, validates, and securely forwards event data to multiple analytics and ad platforms.
- Implementing it requires provisioning a server container, mapping a custom subdomain, and ensuring consent data is correctly propagated and respected.
- Costs typically range from $30 to $50 per month for hosting, with added overhead for server maintenance, monitoring, and cost-effective scaling practices.
- It is most beneficial for high-volume, multi-vendor sites with strict privacy requirements, while small sites with limited tracking may find it unnecessary.
Table of Contents
- What server side tracking is and how it differs from client side tracking
- How server side tracking works: architecture and components
- Benefits and trade-offs for marketing teams
- Setting up server-side tagging with Google Tag Manager: provisioning options and quick steps
- Consent, privacy, and measurement: Consent Mode, GPC/GPP, and passing consent to the server
- Infrastructure, costs, and scaling best practices
- Implementation checklist and common pitfalls
- When we recommend server-side tracking to clients
- How Red Rock Webscapes can help implement server-side tracking
- Sources
- FAQ
What server side tracking is and how it differs from client side tracking
Client-side tracking sends data directly from a visitor’s browser to each vendor: one call to Google Analytics, another to an ad platform, another to a heatmap tool. Every one of those scripts loads independently, competes for bandwidth, and is visible to ad blockers and browser privacy features. Server-side tracking changes that path: the browser sends one event to a server you control, and that server decides what to forward, to whom, and in what shape.
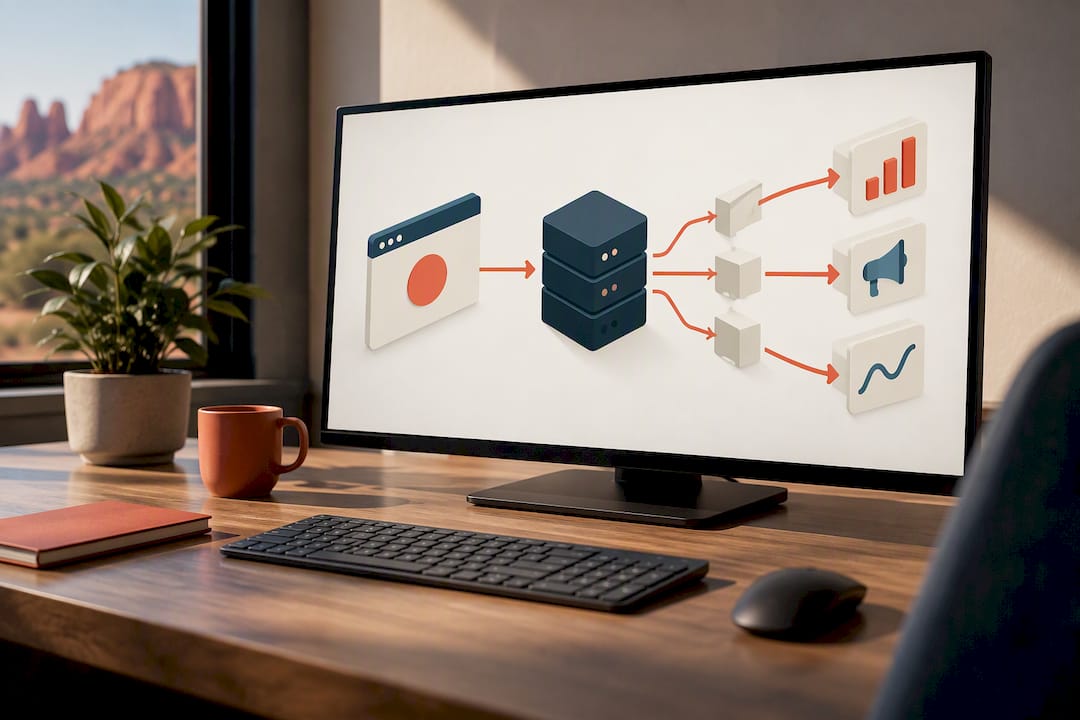
In a Google Tag Manager server-side setup, a web container (the familiar client-side GTM) still fires on the page, but instead of talking to every vendor directly, it sends events to a server container you host. Inside that container, clients receive the incoming request, tags process and forward it, and a custom domain makes the whole exchange look first-party to the browser.
A simple example: a shopper completes checkout. The web container fires one event to your server container. The server container normalizes that event and dispatches it to Google Analytics, an ad platform, and a customer data tool, each formatted the way that vendor expects.
- The browser talks to one endpoint instead of several third-party domains.
- The server decides what data each vendor actually receives.
- A custom subdomain keeps the request looking first-party rather than cross-site.
How server side tracking works: architecture and components
A server container is a self-contained Tag Manager environment running on infrastructure you provision, separate from the web container living in the page. Understanding its parts makes it easier to plan the build with a developer.
- Clients receive incoming HTTP requests and interpret them; a GA4 client, for instance, recognizes requests shaped like Google Analytics hits and “claims” them for processing.
- Tags take the claimed data and forward it to a destination, whether that is Google Analytics, an ad platform, or an internal data warehouse.
- Triggers decide which tags fire for which claimed events, the same logic pattern used in a standard web container.
- A mapped subdomain (something like
metrics.yoursite.com) lets the server container receive requests as first-party traffic, which improves cookie durability and privacy handling.
Because every event passes through one place before it fans out, you can normalize a single checkout event into the exact formats three different vendors expect, strip fields you never intended to share, and log one clean record of what left your server. That single point of control is the practical reason marketing teams move to this model instead of stacking more browser scripts. Server-side tracking also gives you a natural checkpoint to validate data before it becomes a vendor’s problem to clean up.
Benefits and trade-offs for marketing teams
The clearest gain is data quality. Routing events through a server you control means you can validate fields, catch duplicate hits before they inflate conversion counts, and strip personally identifiable information before it ever reaches a third party, a capability Google highlights as a core security benefit of the model. Pages also load faster once several vendor scripts are replaced by a single lightweight call to your own domain.
- Fewer client-side scripts mean less blocking of ad blockers and faster page paint times.
- Centralized processing lets you de-duplicate and validate events before they reach any vendor.
- A custom domain improves cookie durability against browser tracking prevention.
- Combined with Consent Mode, the server becomes the enforcement point for what actually gets sent.
A Cloud Run server instance typically runs $30 to $50 per month, and that is before counting engineering time to configure and maintain it.
The trade-offs are real. Someone has to provision and monitor the server container, map and maintain a custom domain, and keep tag configurations current as vendors change their APIs. For a small brochure site, that overhead rarely pays for itself; for a commerce site running multiple ad platforms and an analytics stack, it usually does.
Setting up server-side tagging with Google Tag Manager: provisioning options and quick steps
Google Tag Manager supports two provisioning paths for the server container, and the right one depends on how much infrastructure work your team wants to own.
- Automatic provisioning on Cloud Run is the fastest path: Tag Manager sets up the Google Cloud project, deploys the container, and handles most of the configuration for you, which suits teams without dedicated DevOps support.
- Manual provisioning on App Engine or another host gives you more control over region, scaling rules, and networking, which suits teams that already run infrastructure on a specific platform.
- Once the container exists, map a subdomain (for example
sgtm.yoursite.com) to it so requests look first-party rather than cross-site, a step Google recommends for better cookie handling. - Use preview mode to confirm events arrive and route correctly before anything goes live.
- Move to production and set your instance count based on expected traffic, then confirm the health check endpoint responds correctly.
Pro Tip: Run the server container in preview mode against a staging page for at least a few days before flipping production traffic over. Consent and payload bugs surface fast under real browsing behavior but rarely show up in a five-minute test.
Most teams get a working container live within a week; the domain mapping and DNS propagation is usually the slowest step, not the tagging configuration itself.
Consent, privacy, and measurement: Consent Mode, GPC/GPP, and passing consent to the server
Server-side tracking only respects user privacy choices if consent state actually reaches the server, which is not automatic. Basic Consent Mode adjusts what the web container sends before it even reaches your server; advanced Consent Mode goes further, letting the server container receive anonymous, cookie-free pings when a user has denied ad_storage or analytics_storage, which supports modeled measurement without setting any cookie on the device.
The pattern that makes this work: every event payload from the browser includes the current consent state, and server tags read that state before firing any vendor call.
- Include
ad_storage,analytics_storage, and any GPC or GPP signal in every payload sent to the server. - Configure each server tag to check consent state before dispatching to a vendor API.
- Treat missing consent fields as a denial, not as an open default.
The most common failure mode in advanced setups is simply forgetting to propagate consent from browser to server, which quietly sends full data to vendors regardless of what the visitor chose.
Infrastructure, costs, and scaling best practices
Budgeting for a server container means accounting for three cost drivers: compute instances, network egress, and logging. A Cloud Run instance runs roughly $30 to $50 per month, and Google recommends running more than one for redundancy so a single instance failure does not drop data.
| Cost driver | Typical guidance |
|---|---|
| Compute instance | $30 to $50 per instance per month |
| Redundancy | Minimum 2 to 3 instances recommended |
| Logging | Filter or disable verbose request logs above 1 million requests per month |
Logging is the driver most teams miss. At high traffic volumes, verbose request logs generate charges that can rival the compute cost itself, so filtering or disabling them once volume grows is standard practice. Beyond cost, keep a health check endpoint monitored, review container image updates on a regular schedule, and consider multi-region deployment only once traffic patterns justify it.
Implementation checklist and common pitfalls
Before writing any configuration, inventory every vendor endpoint currently receiving client-side data so nothing gets dropped in the migration.
- Inventory existing client-side tags and the events each vendor expects to receive.
- Wire consent state into every event payload before touching the server container.
- Provision the server container through Cloud Run or manual hosting.
- Map a custom subdomain and confirm DNS propagation.
- Run preview mode against staging traffic and validate each vendor receives correctly formatted data.
- Move to production and set instance count based on real traffic volume.
The most frequent mistakes: forgetting to include consent fields in the payload, skipping the custom domain mapping step, letting request logging run unfiltered, and under-provisioning instances so the container drops requests during traffic spikes.
Pro Tip: Watch the health check endpoint and request error rate for the first two weeks after launch. A rollout that looks fine on day one can quietly start dropping events once real traffic volume hits it.
When we recommend server-side tracking to clients
Server-side tracking earns its cost when a site runs several ad platforms, needs tighter consent enforcement, or has outgrown what client-side scripts can reliably deliver. For a small brochure site with one analytics tag, it is usually overkill. For a commerce store juggling multiple vendors and consent obligations, it tends to pay for itself in cleaner data alone. We typically bring it into a project once a client’s stack has outgrown simple client-side tagging.
— George
How Red Rock Webscapes can help implement server-side tracking
Setting up a server container is a project most marketing teams would rather hand off than manage in-house, and that is where our development background pays off directly. We handle the parts that trip up most self-managed rollouts: provisioning, custom domain mapping, consent wiring, and the ongoing monitoring that keeps a container healthy after launch.
- Custom domain mapping and server container provisioning handled end to end.
- Consent Mode wiring so browser and server agree on what each visitor allowed.
- Ongoing monitoring and maintenance through our managed care plans.
Our Website Launchpad program includes managed care options like Growth Care and Commerce Care for sites that need this kind of ongoing technical support, and our service packages cover the development work to get a server container live in the first place. Reach out for a quote and we will scope the setup against your current vendor stack.
Sources
- Server-side tagging overview | Google Tag Manager – Server-side
- Server-side vs client-side tracking | Usercentrics
- Google Consent Mode v2, GPC, GPP unified implementation guide | Consenteo
FAQ
What is server-side tracking?
Server-side tracking sends visitor data from the browser to a server you control first, which then forwards it to analytics and ad vendors instead of the browser contacting each vendor directly. This setup, described in Google’s overview, gives you a checkpoint to validate, clean, and route data before it leaves your infrastructure.
What is the server-side tracking process?
The browser sends one event to your server container, where a client receives and identifies the request, tags process it, and the server forwards a formatted version to each vendor endpoint. Mapping a custom subdomain to the container keeps this exchange first-party from the browser’s perspective.
Is server-side tracking legal?
Server-side tracking itself is a data architecture choice, not a legal status, so its legality depends on whether the data collected respects applicable privacy rules and user consent. Pairing it with Consent Mode so the server only sends data users have agreed to is the practical way most sites stay compliant.
What is the difference between client-side and server-side tracking?
Client-side tracking sends data straight from the browser to each vendor separately, while server-side tracking routes everything through one server you control before it reaches vendors. That extra step, outlined in Usercentrics’ comparison, lets you validate and filter data centrally instead of trusting each vendor script individually.